
Introducing Bespoke Nimble: an open data, open model, open recipe for an open Jev.
Code and info: https://github.com/bespokelabsai/nimble
Model: https://huggingface.co/bespokelabs/Bespoke-Nimble-9B
Data:
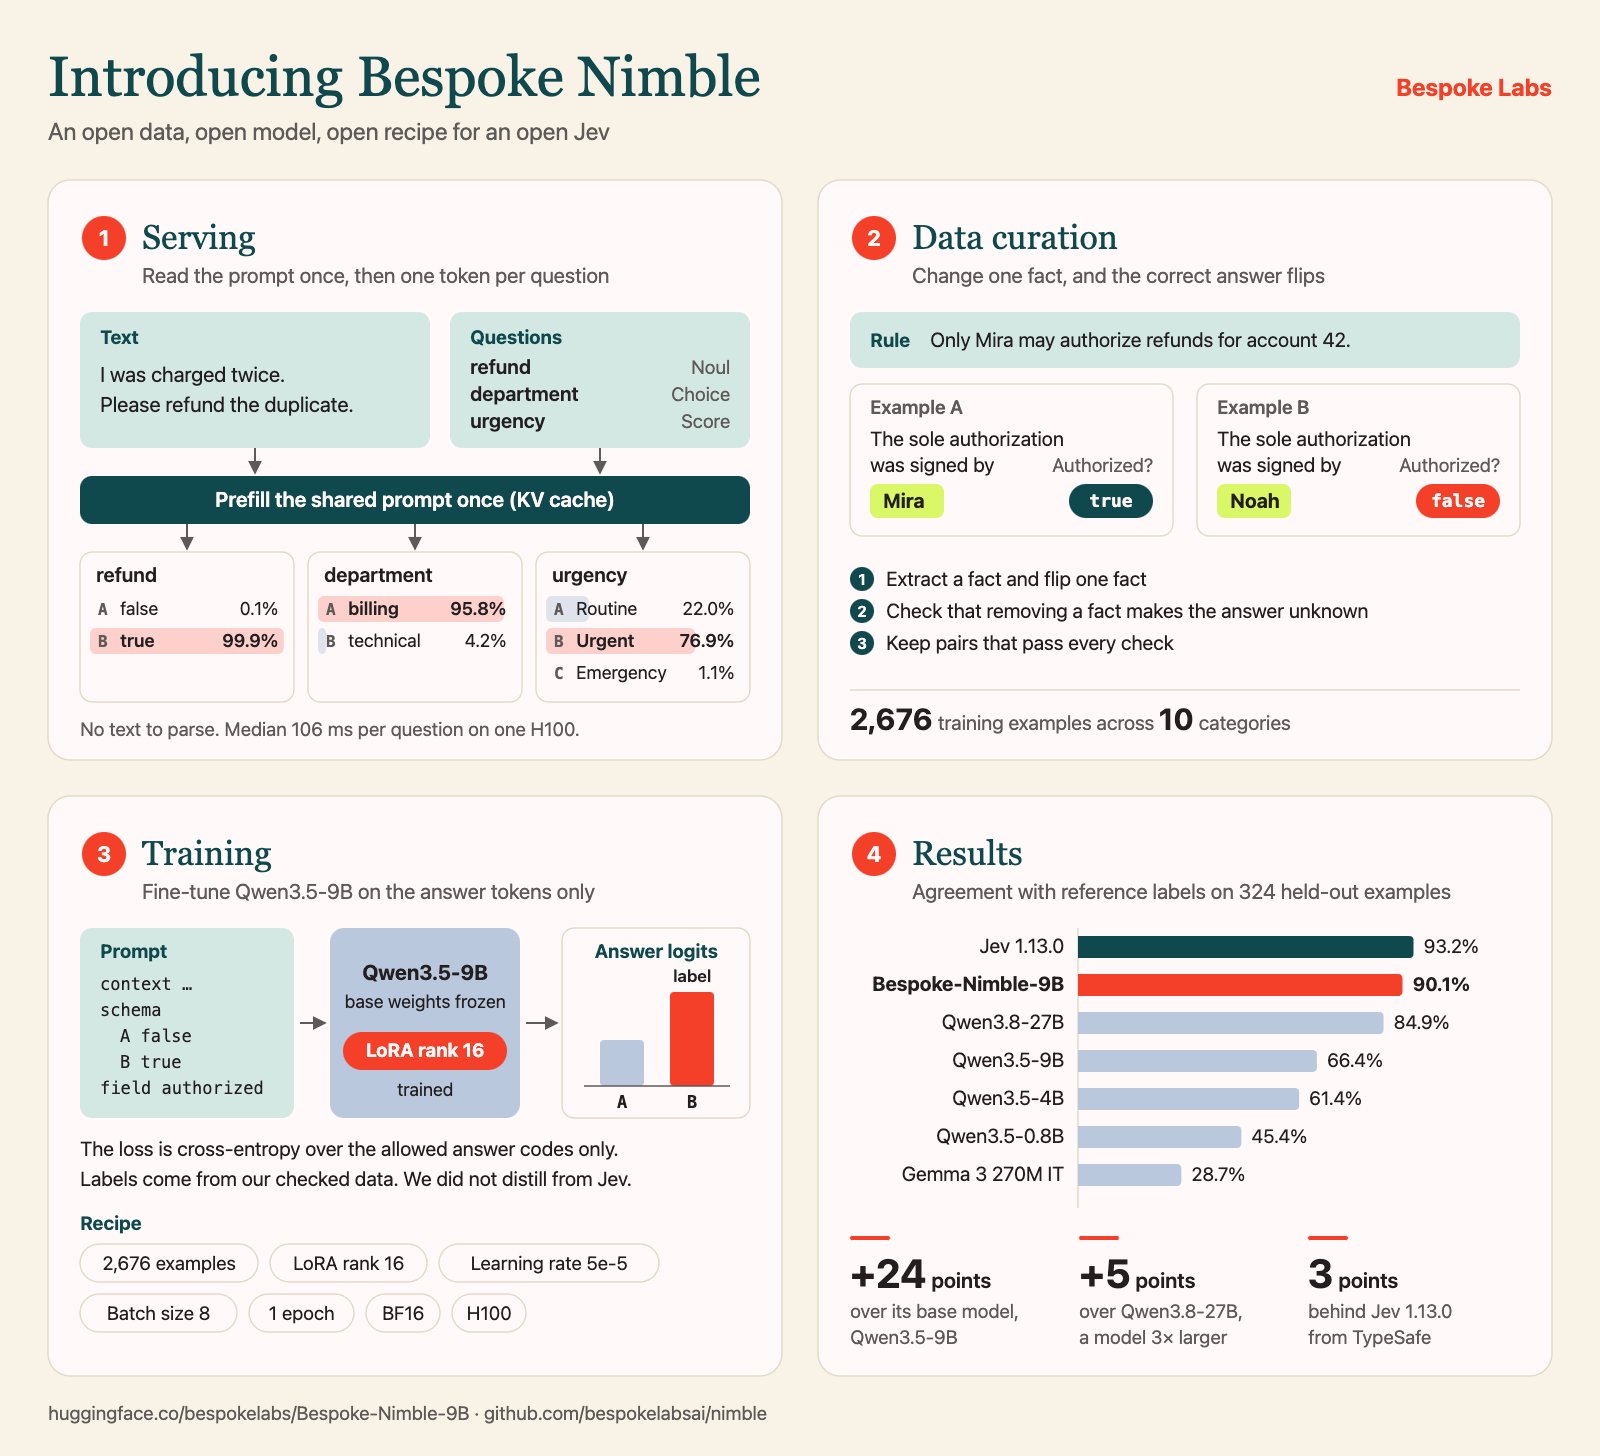
* A new data curation recipe called contrastive data curation.
* Slightly change facts to generate negative data. This pushes the model to discriminate better and become a better decision maker. The calibration is implicit.
* Didn't do ablations but I think this is a critical piece!
* This also means training data doesn't need probabilities.
* Data covered 10 categories, and is fully synthetic.
* This data is split into train and eval.
Training
* LoRA finetune of Qwen3.5-9B.
* Distillation-free: we use Jev to only evaluate.
* No RL yet!
Serving
* Parallel constrained decoding as suggested by @NielsRogge and @harshagundal.
Results:
* The post-trained Qwen (Nimble) became substantially better on our curated eval: 66% for Qwen to 90% for Nimble. Jev is at 93%.
* 100ms on H100 and free to use on your macbook! Feel the AGI for free.
* 2 days of building in public. :)
Big caveat is that there is no standard benchmark to measure performance, and it's possible Nimble is much worse on other benchmarks compared to Jev. But it should be better than Qwen!
We thank @typesafeai for making Jev and the inspiring discussions in the community. Hope this release lifts all the boats and encourages more research and activity in this space.